Combinatorial chemistry
Parallel synthesis builds large, diverse small molecule libraries around scaffolds chosen by the model. Chemistry is constrained by what can actually be made at scale.
Millions of compounds per cycle
1859 appoints Dr. Helena Marsh as Chief Scientific Officer — read the announcement
Small molecule therapeutics
Our engine integrates combinatorial chemistry, pico-scale activity-based screening and machine learning. Every week it produces millions of empirical datapoints, and every week those datapoints make our models better at finding molecules that matter.
Founded 2019 · San Diego, California · Backed by a $40 million Series A
Investors & scientific collaborators
The premise
Most machine learning in drug discovery is trained on data that was generated for a different purpose. We build the assays, the libraries and the models together, so that every experiment is designed to teach the model something it does not already know.
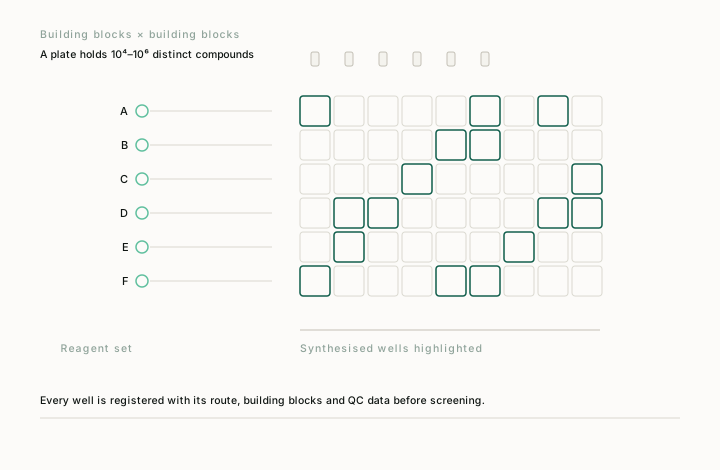
Parallel synthesis builds large, diverse small molecule libraries around scaffolds chosen by the model. Chemistry is constrained by what can actually be made at scale.
Millions of compounds per cycle
Activity-based assays run at pico-scale, so a cycle costs a fraction of a conventional screen and returns real biochemical or cell-based measurements rather than predictions.
Biochemical and cell-based readouts
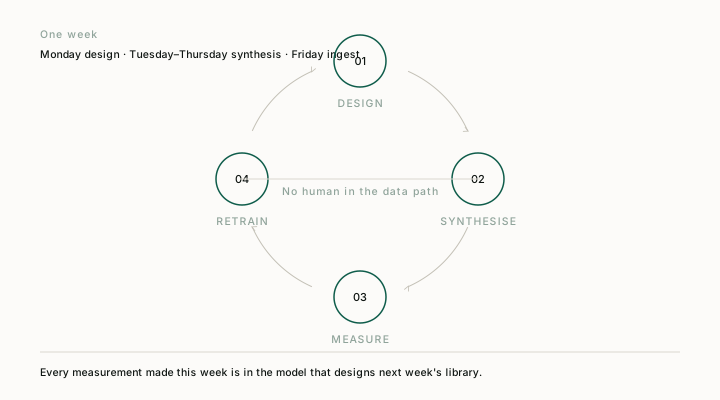
Results feed back into structure–activity models within the same cycle. The next library is designed from what the last one revealed.
Retrained weekly, not quarterly
Why it compounds
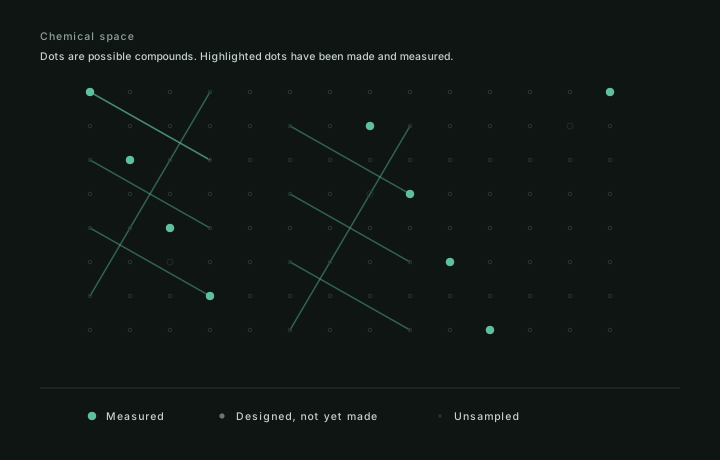
Predictive models degrade when the chemistry they are applied to drifts away from the chemistry they were trained on. By generating our own training data — and by choosing what to make based on model uncertainty — we keep the distribution of our experiments aligned with the questions we are actually asking.
Empirical datapoints generated per week
Rolling weekly average since platform launch. Representative figures.
Data engine
The platform runs continuously. Libraries are synthesised, screened and scored on a weekly cadence, and the resulting measurements are the only currency our models trade in.
| Stage | Output | Cadence | Readout |
|---|---|---|---|
| Library synthesis | ~1.0M compounds | Weekly | LC-MS QC |
| Pico-scale biochemical assay | ~2.4M datapoints | Weekly | IC₅₀, % inhibition |
| Cell-based assay | ~180k datapoints | Weekly | Potency, selectivity |
| Model retraining | Full ensemble | Weekly | SAR, ADME prediction |
| Candidate nomination | 1–3 series | Per programme | Chemistry + biology review |
Representative throughput of the integrated platform.
Pipeline
| Programme | Target class | Area | Stage |
|---|---|---|---|
| 1859-1041 | Kinase | Oncology | Lead optimisation |
| 1859-2087 | GPCR | Inflammation | Lead optimisation |
| 1859-3012 | Ion channel | Neuroscience | Lead identification |
| 1859-3044 | Protease | Oncology | Lead identification |
| 1859-4009 | Undisclosed | Inflammation | Hit expansion |
| 1859-5023 | Undisclosed | Neuroscience | Hit expansion |
“The question is not whether a model can propose a molecule. It is whether we can measure, quickly and honestly, whether the molecule does anything.”
Careers
Principal Scientist, Medicinal Chemistry
ChemistrySenior Scientist, Assay Development
BiologyMachine Learning Engineer, Structure–Activity Models
Data & MLAutomation Engineer, Screening Operations
PlatformProgramme milestones, publications and platform news. No promotional mail.
Thank you — please confirm via the email we just sent.